Should you block AI bots from your site?
It depends which ones, and most advice treats three different things as one. Training crawlers collect pages for building models, search crawlers decide whether an assistant can find and cite you, and user-triggered fetchers read a page because a person asked. Blocking each has a different consequence, and some of them do not follow robots.txt at all. What the AI companies say about each, what Google says about Google-Extended, and how to decide.
It depends which ones, and most advice treats three different things as one. Training crawlers collect pages that may be used to build AI models. Search crawlers decide whether an assistant can find your site and cite it in answers. User-triggered fetchers read a page because a person asked the assistant to. Blocking a training crawler does not remove you from AI search, according to the companies that run them. Blocking a search crawler can: OpenAI says you will not be shown in ChatGPT search answers, and Anthropic says it may reduce your visibility in Claude's. And user-triggered fetches may not follow robots.txt at all.
This is part of our series checking what small businesses are told about marketing, where every claim is tested against what the company running the system publishes.
The three kinds, company by company
Each company publishes the names its bots use. These are the ones in each company's own documentation, read on 27 September 2026 (OpenAI; Anthropic; Perplexity; Google, common crawlers; Google, user-triggered fetchers; Apple).
| Company | Training | Search | User-triggered |
|---|---|---|---|
| OpenAI | GPTBot | OAI-SearchBot | ChatGPT-User |
| Anthropic | ClaudeBot | Claude-SearchBot | Claude-User |
| Perplexity | None listed; PerplexityBot "is not used to crawl content for AI foundation models" | PerplexityBot | Perplexity-User |
| Google-Extended (a control, not a separate crawler) | Googlebot, which also serves AI Overviews and AI Mode | Several, including Google-Agent | |
| Apple | Applebot-Extended (a control, not a separate crawler) | Applebot | None listed |
Google and Apple do not run separate training crawlers. Google-Extended and Applebot-Extended are names you use in robots.txt to say how content their ordinary crawlers collect may be used. Google says Google-Extended "doesn't have a separate HTTP request user agent string" (Google, common crawlers, updated 14 July 2026), and Apple says Applebot-Extended "does not crawl webpages" (Apple, about Applebot).
Blocking training crawlers
This is the one most people mean when they say "block AI bots". The companies say it is separate from search.
- OpenAI says each of its settings "is independent of the others", so a site can allow OAI-SearchBot "in order to appear in search results while disallowing GPTBot to indicate that crawled content should not be used for training" (OpenAI, overview of OpenAI crawlers).
- Anthropic says that when a site restricts ClaudeBot, "it signals that the site's future materials should be excluded from our AI model training datasets" (Anthropic, does Anthropic crawl data from the web).
- Apple says pages that disallow Applebot-Extended "can still be included in search results" (Apple, about Applebot).
What none of them says is whether blocking training changes how their assistants describe or recommend your business. Nobody has published that, so the evidence here is thin. Blocking training crawlers is a reasonable choice about how your content is used. It is not a way to become more or less visible, as far as anything published shows.
What Google says about Google-Extended
Google-Extended is the one where the details matter most, because it is often described as "blocking Google's AI".
Google says Google-Extended lets publishers manage whether content Google crawls "may be used for training future generations of Gemini models that power Gemini Apps and Vertex AI API for Gemini and for grounding (providing content from the Google Search index to the model at prompt time to improve factuality and relevancy) in Gemini Apps and Grounding with Google Search on Vertex AI" (Google, common crawlers).
Two things follow from that.
It does not touch Search. Google says: "Google-Extended does not impact a site's inclusion in Google Search nor is it used as a ranking signal in Google Search" (Google, common crawlers).
It does not remove you from AI Overviews or AI Mode, but it does reach beyond training. AI Overviews and AI Mode are part of Search, which Googlebot crawls. Google says "robots.txt directives for Googlebot is the control" for Search, and points to Google-Extended only "to limit AI training and grounding in some of Google's other systems" (Google, AI features and your website). Blocking Google-Extended also stops your pages being used to ground answers in the Gemini app. So it is not a pure training opt-out.
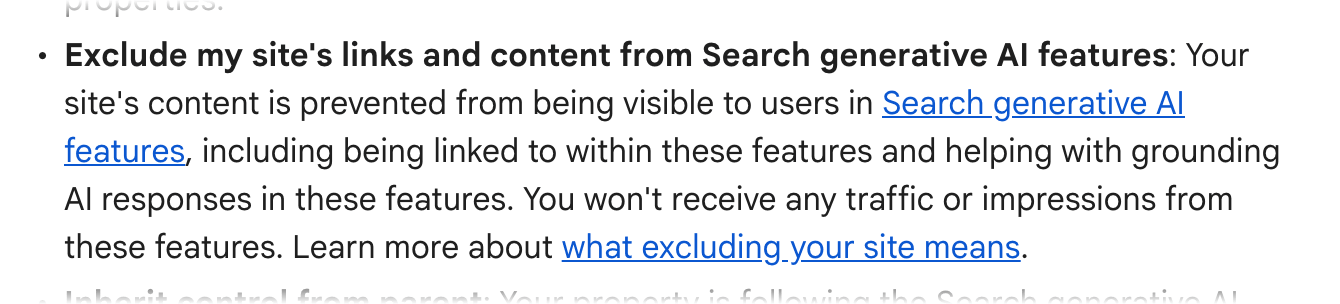
Since 31 August 2026, every site has had a separate switch for Search. The Search generative AI control in Search Console lets a site exclude its links and content from AI Overviews, AI Mode and generative AI features in Discover (Search Console Help, Search generative AI control). Google says excluding means "You won't receive any traffic or impressions from these features", that the control "isn't used as a ranking or inclusion signal affecting other parts of Search", and that it "doesn't affect AI training; to limit training of the models used to generate responses in Search generative AI features, use Google-Extended". The default is to include.
Blocking search crawlers
This is the block that costs visibility, and the companies say so, some more firmly than others.
- OpenAI: "Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers, though can still appear as navigational links" (OpenAI, overview of OpenAI crawlers).
- Anthropic: disabling Claude-SearchBot "prevents our system from indexing your content for search optimization, which may reduce your site's visibility and accuracy in user search results" (Anthropic, does Anthropic crawl data from the web).
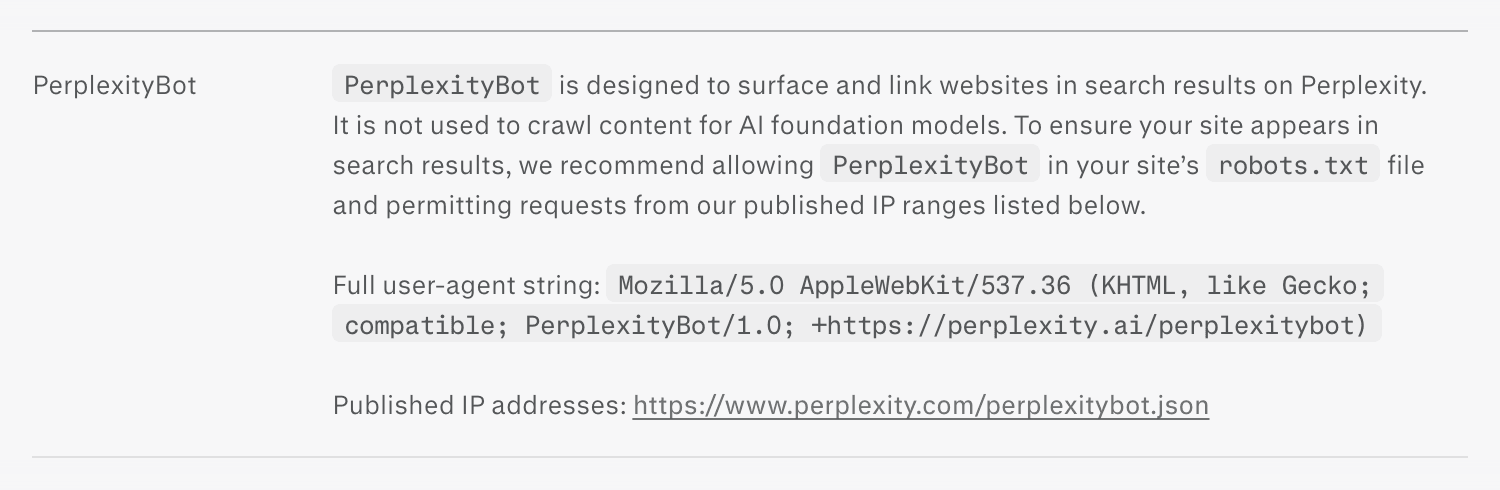
- Perplexity: "To ensure your site appears in search results, we recommend allowing PerplexityBot" (Perplexity crawlers).
- Google and Bing: there is no separate AI search crawler to block. Blocking Googlebot or Bingbot takes you out of their search results as well as their AI features. Bing lists "Blocking Bingbot in your robots.txt file" among the things to avoid, and says the NOARCHIVE tag "prevents content from being used in Copilot responses and grounding results" (Bing Webmaster Guidelines, sections 8 and 10).

For a business that wants to be found, blocking these is the mistake. Our piece on whether ChatGPT is recommending your competitors covers what else decides whether you are named.
User-triggered fetches
When someone pastes your web address into an assistant, or asks it to check your prices, the assistant may fetch the page there and then. The companies treat these fetches differently from crawling, and most say robots.txt may not stop them.
- OpenAI says ChatGPT-User "is not used for crawling the web in an automatic fashion. Because these actions are initiated by a user, robots.txt rules may not apply" (OpenAI, overview of OpenAI crawlers).
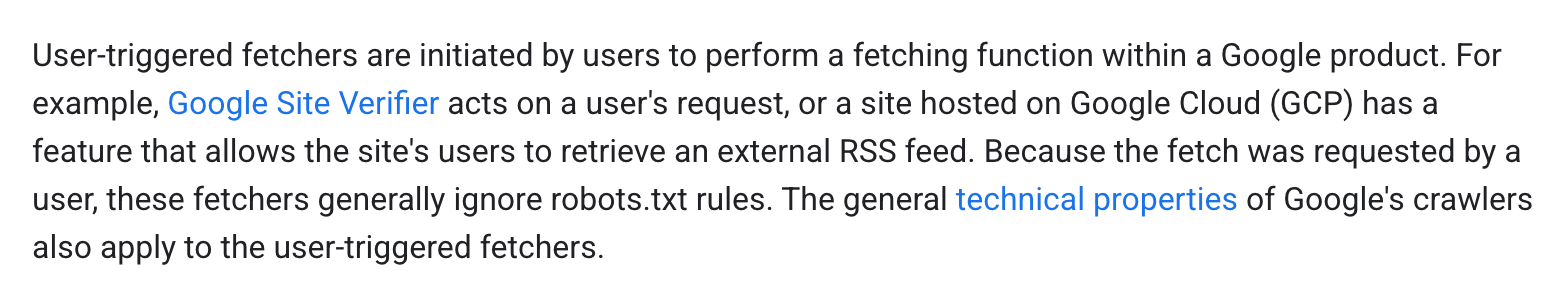
- Perplexity says of Perplexity-User: "Since a user requested the fetch, this fetcher generally ignores robots.txt rules" (Perplexity crawlers).
- Google says its user-triggered fetchers, which include Google-Agent for "agents hosted on Google infrastructure", "generally ignore robots.txt rules" because "the fetch was requested by a user" (Google, user-triggered fetchers, updated 19 August 2026).
- Anthropic is the exception. It says its bots honour robots.txt, and that "Disabling Claude-User on your site prevents our system from retrieving your content in response to a user query, which may reduce your site's visibility for user-directed web search" (Anthropic, does Anthropic crawl data from the web).
So robots.txt is not a reliable way to stop these fetches. A firewall rule can stop them, but think about who triggers them. It is usually a person asking about your business: a potential customer checking your opening hours, your prices, or whether you cover their area. Blocking the fetch means the assistant cannot read your page for them, and answers from whatever else it can find.
You may already be blocking some of them
Many sites block AI bots without anyone deciding to.
- Your robots.txt file. Anyone can read it at your domain followed by
/robots.txt. Look for the names in the table above withDisallow: /under them, and for aUser-agent: *group that disallows everything. - Your network or firewall service. Cloudflare's documentation said that on 15 September 2026 it would change its defaults for new domains, so that "bots classified as Training or as Agent" are blocked on pages that display ads, while "Search will remain allowed". Its Agent category covers "automated activity acting in real time on a person's behalf, such as chat fetch bots" (Cloudflare, AI bot policies). Other services have their own settings; check whichever sits in front of your site.
- Security plugins and hosting. Perplexity's documentation notes that a web application firewall may need to explicitly allow its bots (Perplexity crawlers).
If a site is missing from AI answers, a block like this is one of the first things to rule out, alongside the checks in our guide to why a website is not showing up on Google.
How to decide
For most small businesses that want to be found, the published evidence points one way:
- Allow the search crawlers: OAI-SearchBot, Claude-SearchBot, PerplexityBot, Googlebot and Bingbot.
- Do not block user-triggered fetchers unless you have a specific reason, such as load on the server. They mostly act for people asking about you.
- Decide on training crawlers (GPTBot, ClaudeBot, Google-Extended, Applebot-Extended) as a question about how your content is used, not about visibility.
- If you block Google-Extended, know that it also stops your pages being used to ground Gemini app answers.
- If you want out of AI Overviews and AI Mode, use the Search generative AI control in Search Console, and expect to lose that traffic.
- Check your firewall or network service settings, not only robots.txt.
- Afterwards, check what the platforms report: Bing's AI Performance report and Search Console's Generative AI performance report.
Publishers whose content is the product, such as news or paid research, may weigh training differently, and that is a legitimate business decision. It is a different decision from wanting a local business to be found.
Our interest
We sell AI search visibility work, so we have an interest in sites being findable. Our own site allows every AI crawler named above, training crawlers included. That is a choice, not a tactic: nothing published says allowing training crawlers improves recommendations. If you are not sure what your site is blocking, ask us and we will check.
Where the evidence is thin
- No AI company publishes whether blocking its training crawler changes how its assistant describes or recommends a business.
- OpenAI says robots.txt rules "may not apply" to ChatGPT-User, without saying when they do.
- We have not checked the default bot settings of every hosting, security or network service. Only Cloudflare's are cited here.
The verdict
It depends which ones. Blocking training crawlers is a reasonable choice about how your content is used, and the companies say it does not remove you from their search. Blocking search crawlers costs visibility in AI answers, and blocking Googlebot or Bingbot costs you search as well. User-triggered fetches may ignore robots.txt, and blocking them at a firewall stops an assistant reading your page for the person who asked. For a small business that wants to be found, the published evidence says let the search crawlers in.
Questions people ask
If I block GPTBot, will my site disappear from ChatGPT?
Not from ChatGPT search. OpenAI says each of its robots.txt settings is independent: blocking GPTBot tells it not to use your content to train its models, while OAI-SearchBot controls whether your site can appear in ChatGPT search answers.
Does blocking Google-Extended remove my site from Google Search or AI Overviews?
No. Google says Google-Extended does not affect a site's inclusion in Google Search and is not a ranking signal. It controls use of your content for training Gemini models and for grounding in Gemini Apps and Vertex AI. AI Overviews and AI Mode are part of Search and are controlled separately, through the Search generative AI control in Search Console or snippet controls.
Can I stop ChatGPT or Perplexity reading my page when someone asks about it?
Not reliably with robots.txt. OpenAI says robots.txt rules may not apply to ChatGPT-User, and Perplexity says Perplexity-User generally ignores robots.txt, because a person asked for the fetch. Anthropic says Claude-User follows robots.txt. Blocking these fetches at a firewall is possible, but it also stops the assistant reading your page for a potential customer.
Should a small business block AI training crawlers?
It is a choice, not a visibility tactic. The AI companies say training crawlers are separate from search, and none of them publishes whether allowing or blocking training changes how an assistant describes or recommends a business.
Could I be blocking AI bots without knowing?
Yes. Check your robots.txt file and any firewall or network service in front of your site. Cloudflare, for example, said it would change its defaults for new domains from 15 September 2026, so that AI training and agent traffic is blocked on pages that display ads.
I run oXo Creatives full-time: an independent, founder-led marketing agency and consultancy that I founded in 2013. Until 2026 I ran it alongside senior in-house roles at Google, NatWest, King, PlayStation and Meta.
Want help with aI search visibility?
Find out what ChatGPT, Claude and Gemini say when someone asks for a business like yours, fix what they get wrong or cannot find, and check again to see what moved. Nobody can promise that an assistant will recommend you, and we do not. The free check is immediate. The fix list takes about a week, and the fixes themselves depend on how much needs changing.